I am a Ph.D. candidate at Harbin Institute of Technology (Shenzhen), advised by Haijun Zhang. I also work with Xin Li and Ming-Hsuan Yang.
My research focuses on video segmentation, generative video editing, and streaming video understanding. I am currently an algorithm research intern at ByteDance.
🔥 News
- 2026.10: New papers and project pages: DeOverlay / DVTE-Bench, TCoVP, and DeltaStreamer.
- 2026.06: 🏆 Our APRVOS solution won 1st place in the MeViS-Audio track of the 5th PVUW Challenge at CVPR 2026.
- 2026.05: GeoWeaver and RCoT-Seg are available on arXiv.
- 2026.02: SGAFuse was published online in Neural Networks.
- 2025.07: 🏆 Winner of the VOTS 2025 Challenge (VOTS, VOTS-RT, and VOTSt tracks).
- 2025.01: One paper accepted to ICLR 2025.
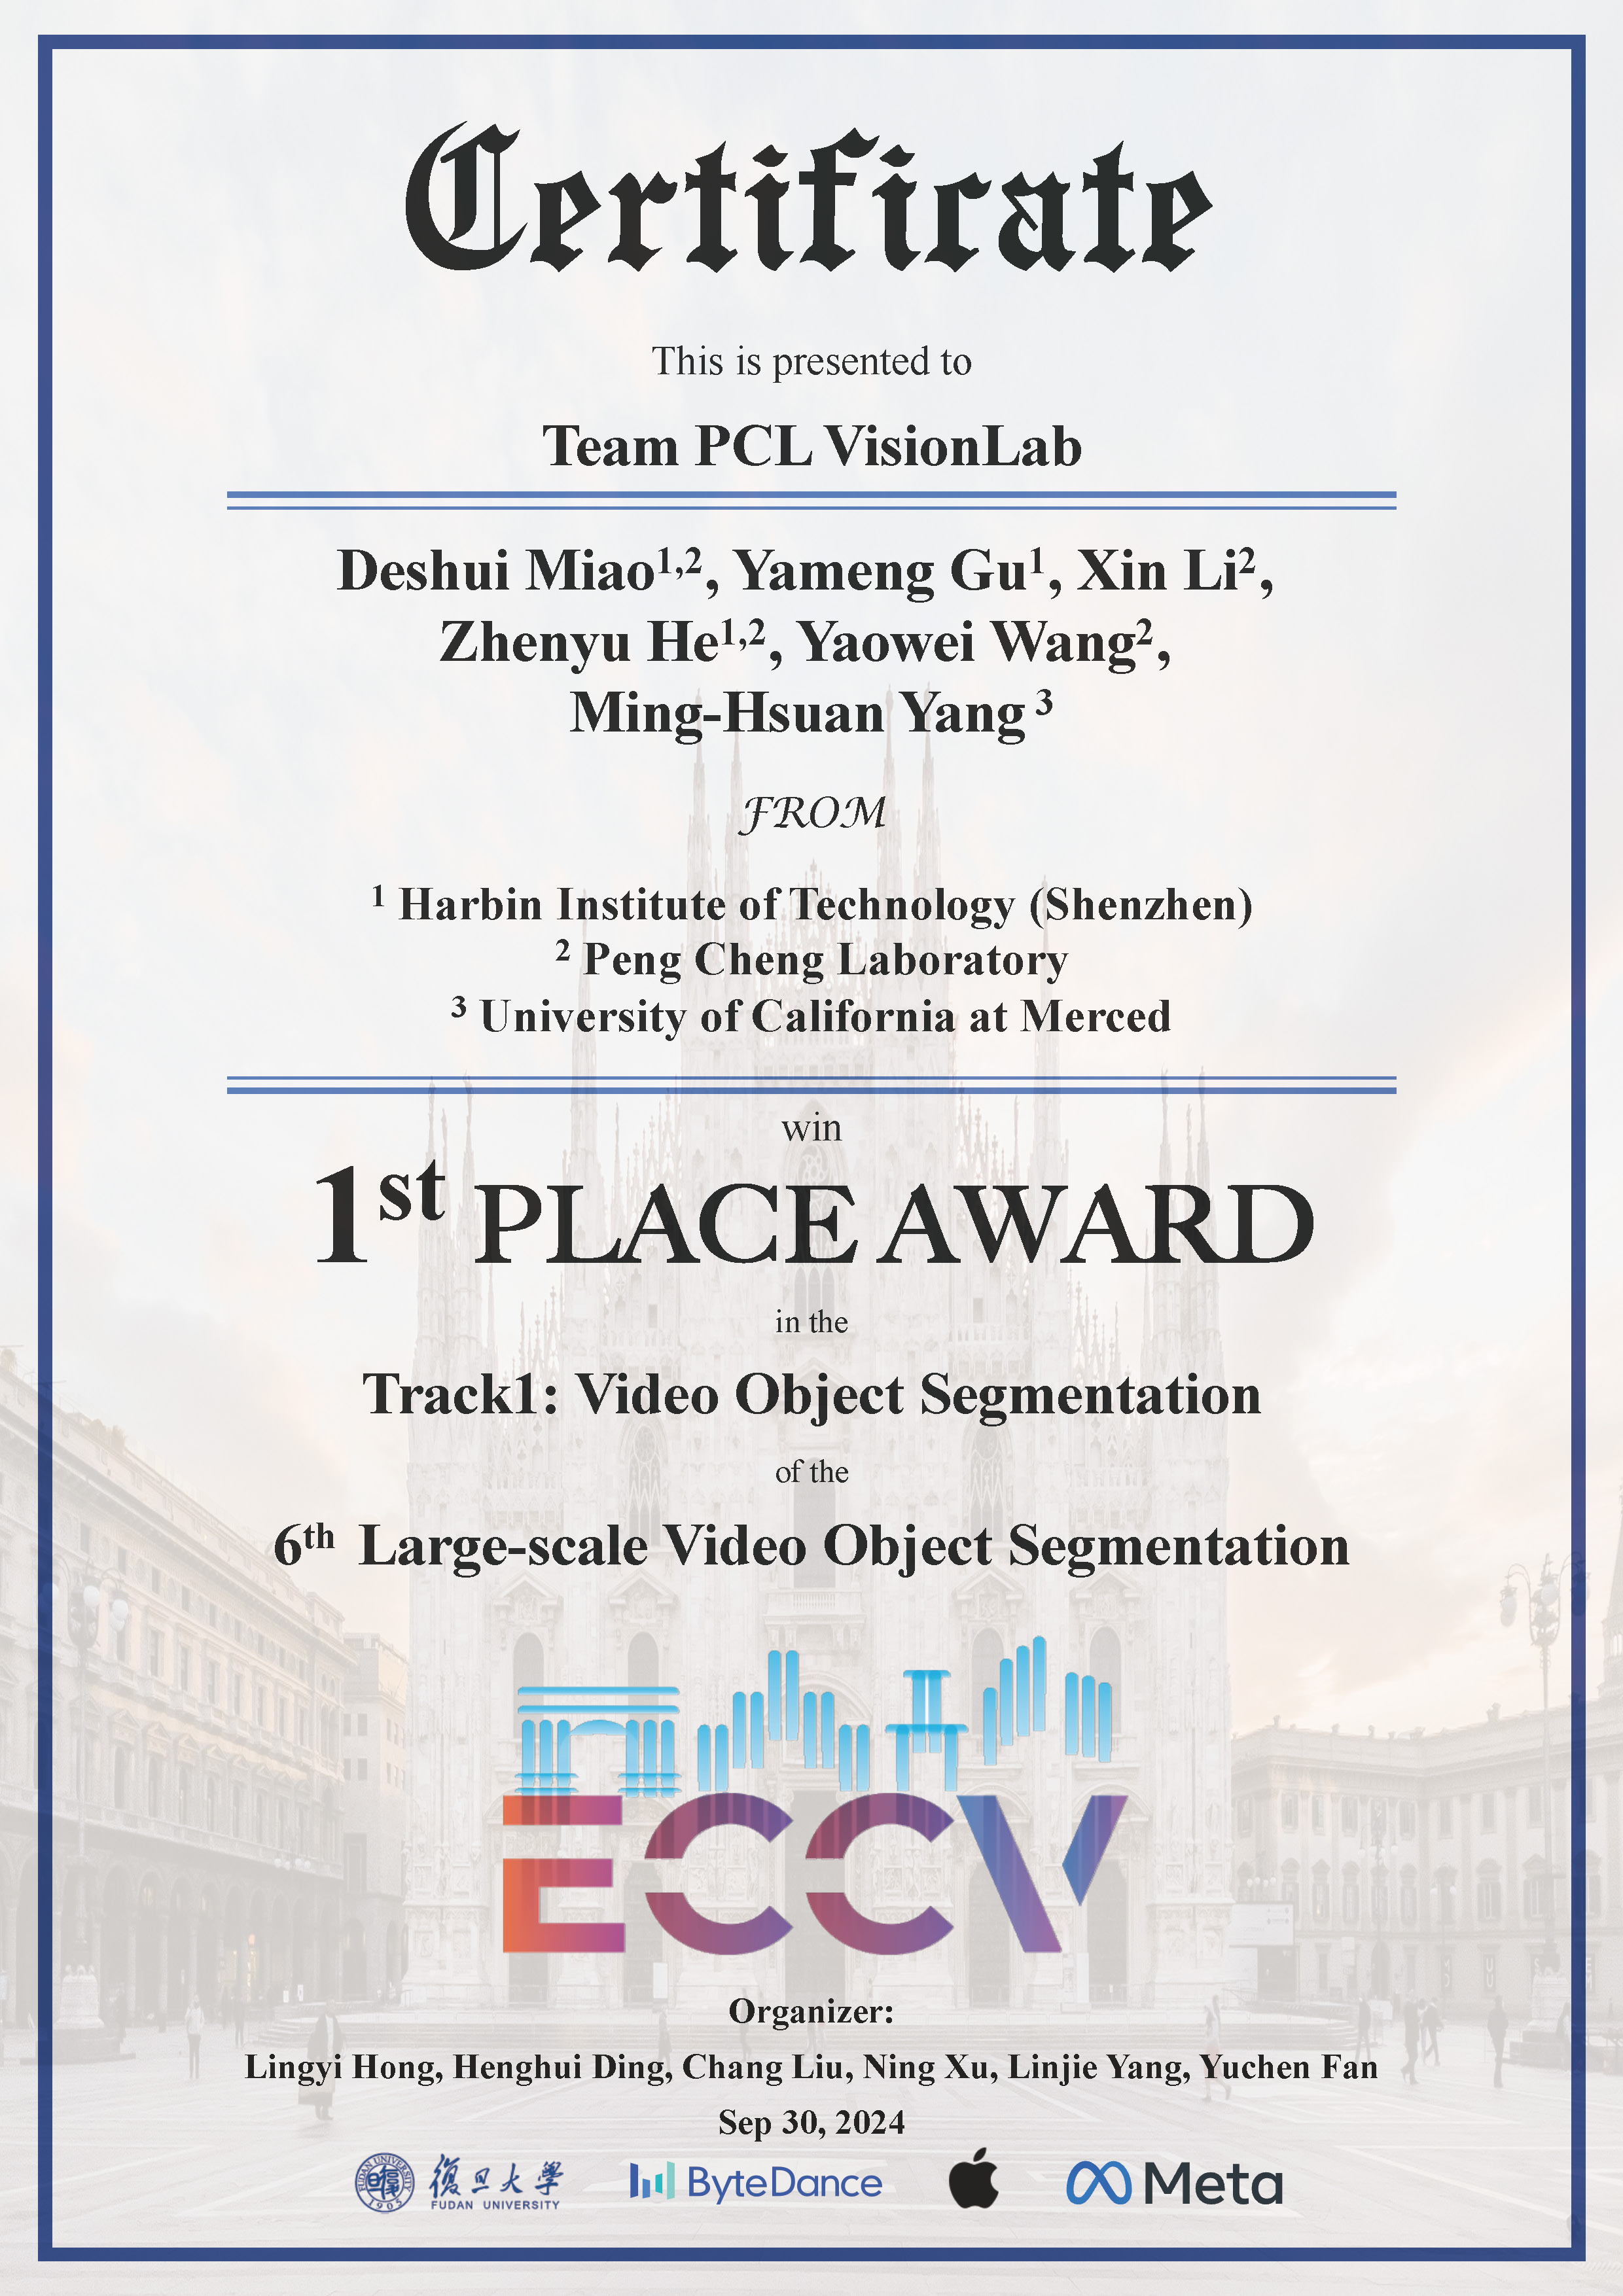
- 2024.08: 🏆 Winner of the LSVOS V6 Challenge (VOS track).
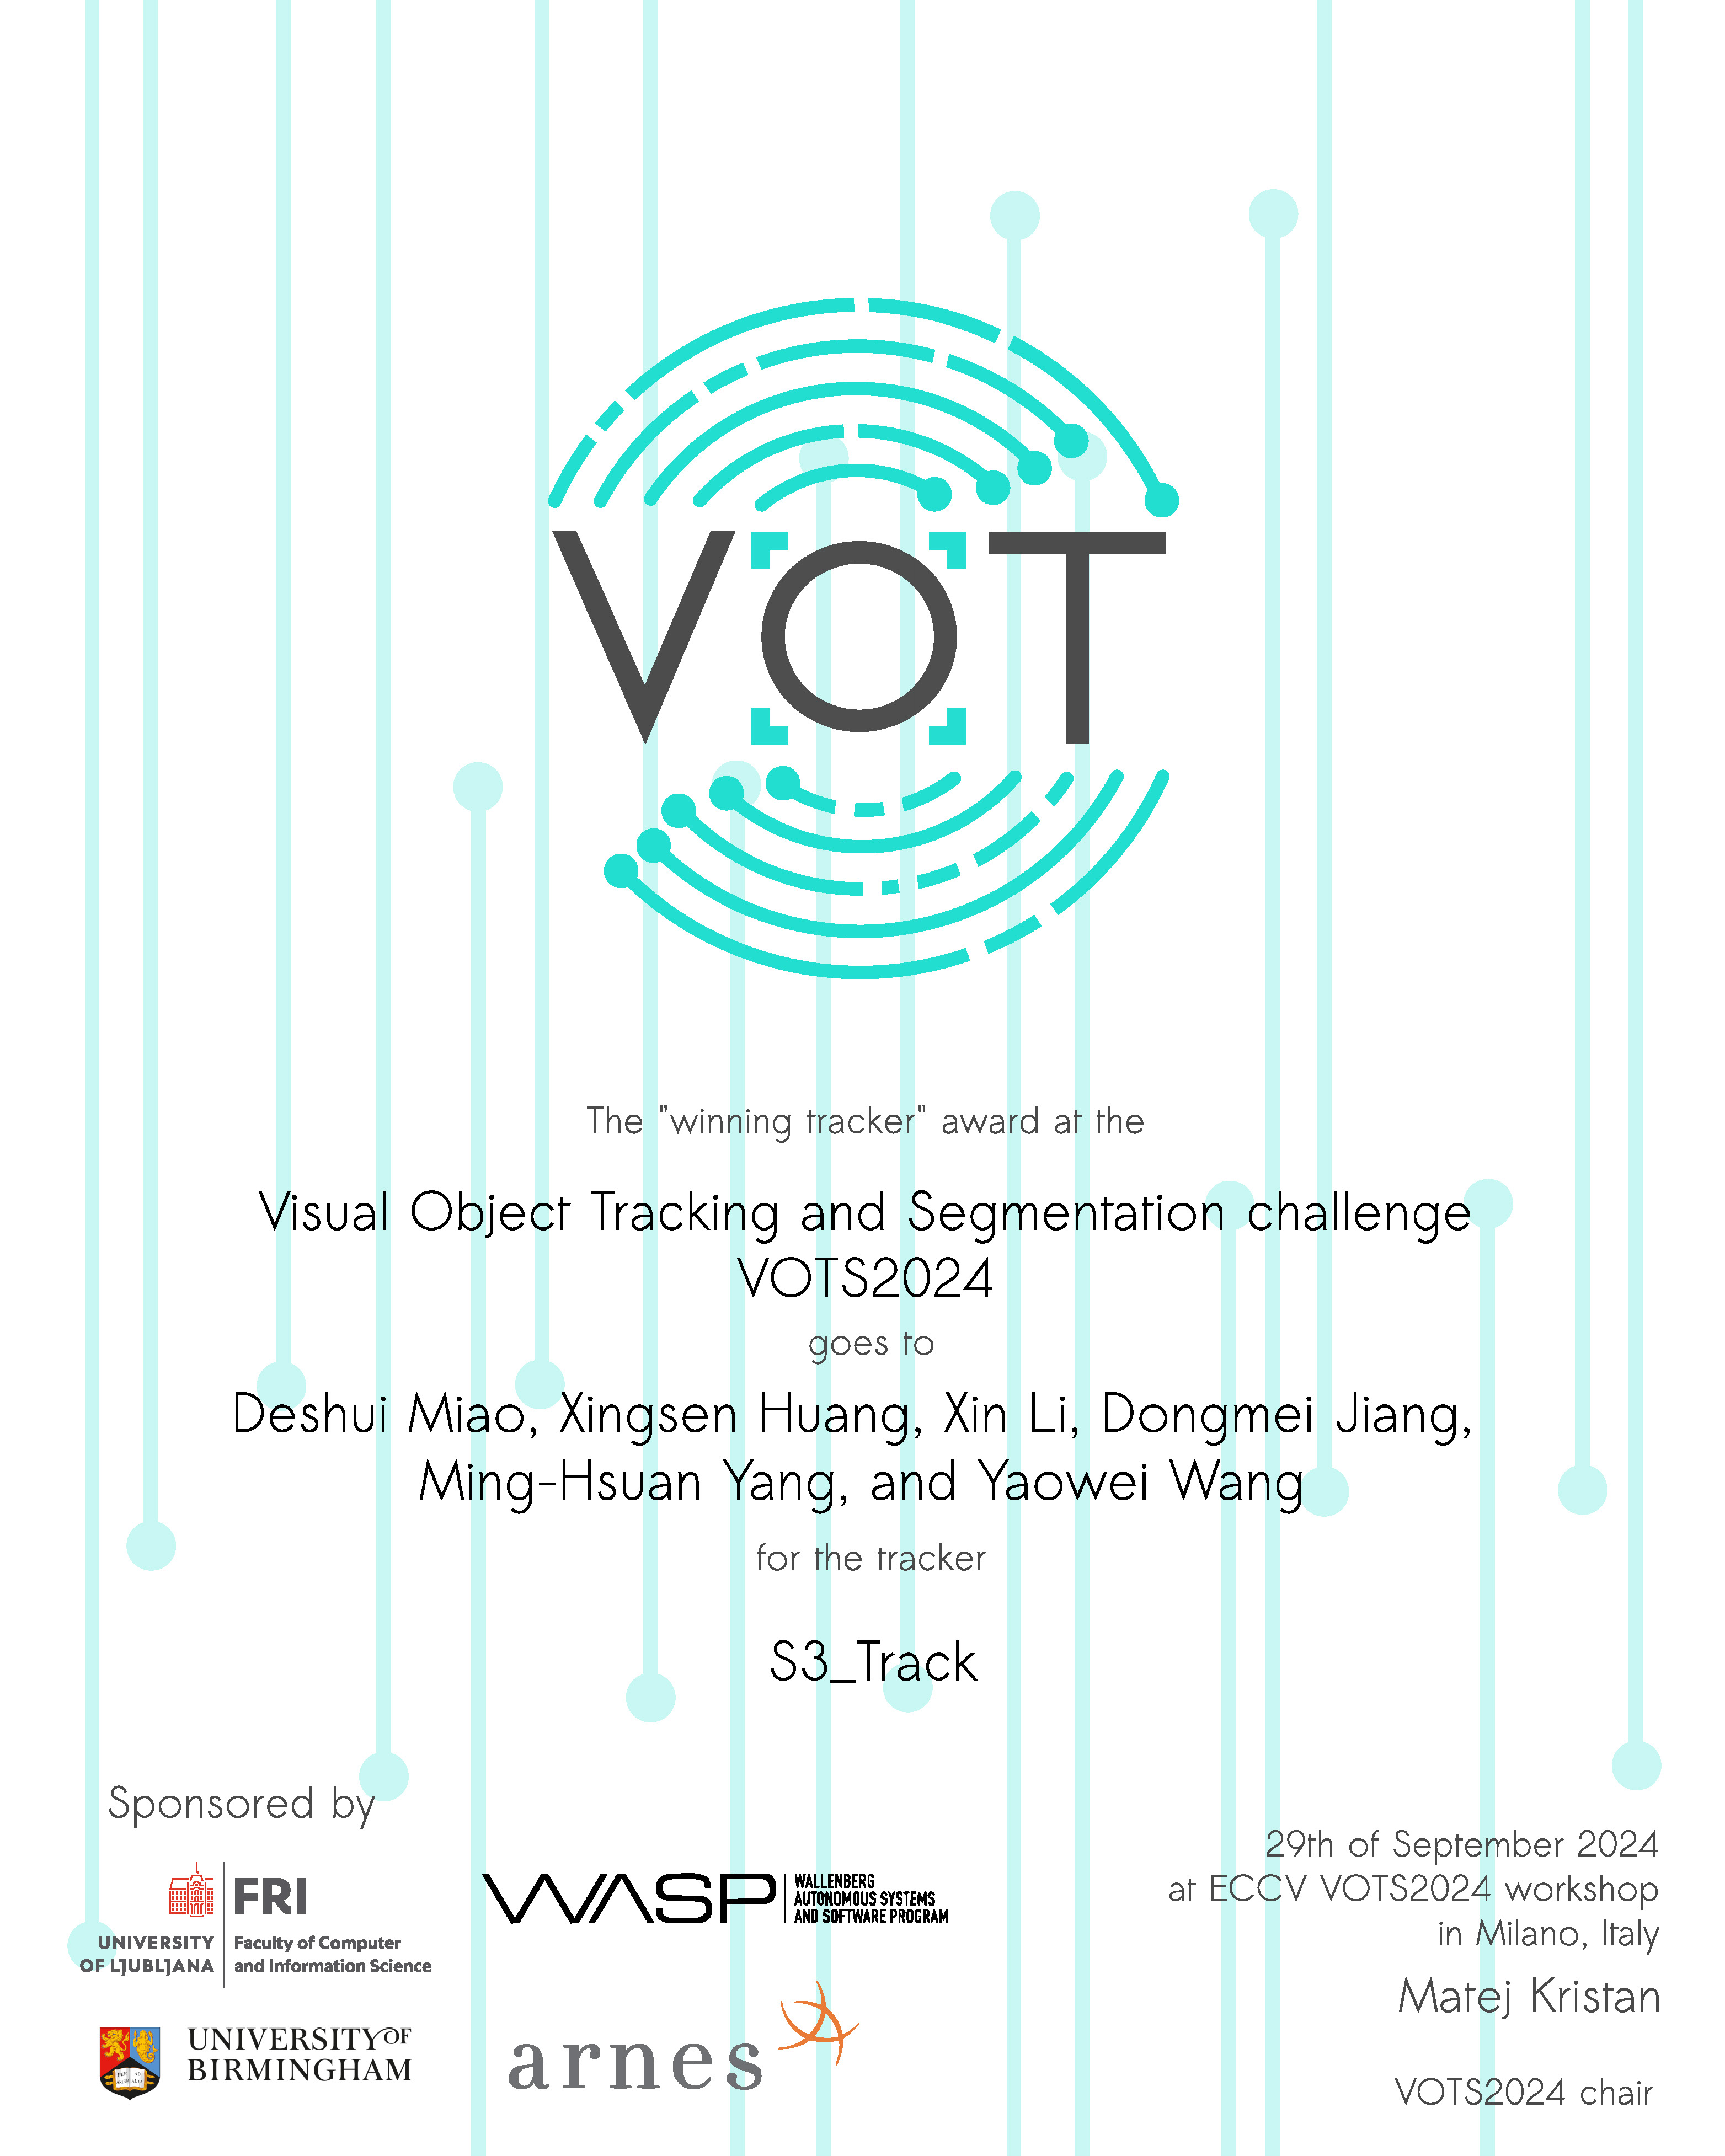
- 2024.07: 🏆 Winner of the VOTS 2024 Challenge; one paper accepted to ECCV 2024.
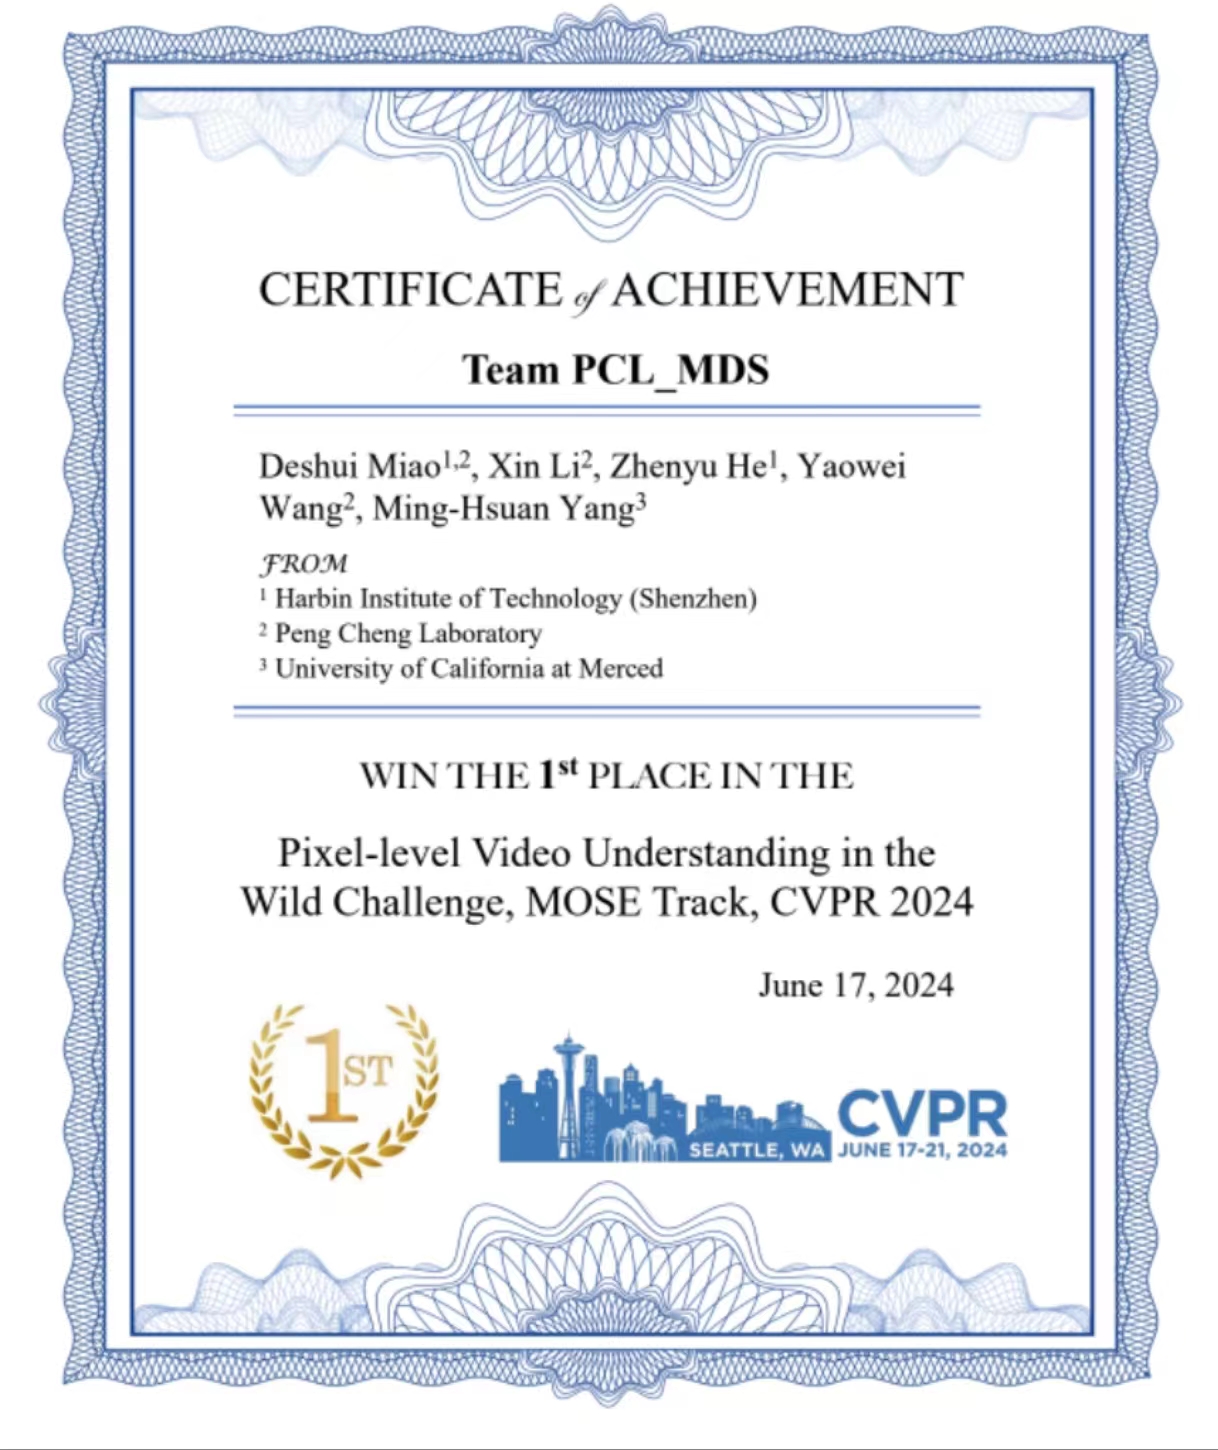
- 2024.06: 🏆 Winner of the 3rd PVUW Challenge at CVPR 2024 (MOSE track).
- 2024.03: One paper accepted to IEEE TMM.
- 2023.08: 2nd place in the 5th LSVOS Challenge (VOS track).
📝 Publications
2026
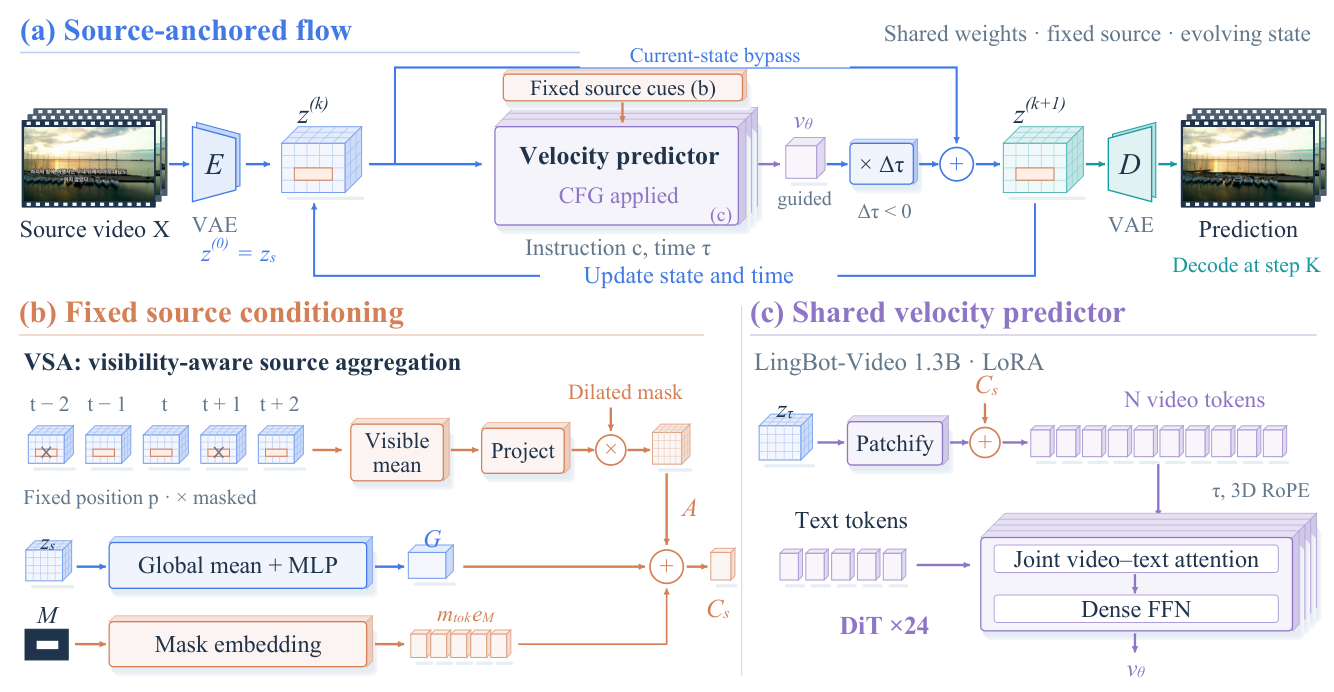
DeOverlay: A Benchmark and Source-Anchored Flow for Video Overlay Removal
A source-anchored flow model removes video overlays, evaluated with DVTE-Bench across eight text-overlay categories.
Think Visually Across Space and Time: Grounded Reasoning for Video Segmentation
Temporal Chain of Video Primitives connects entity identity, temporal support and spatial evidence for grounded video reasoning segmentation.
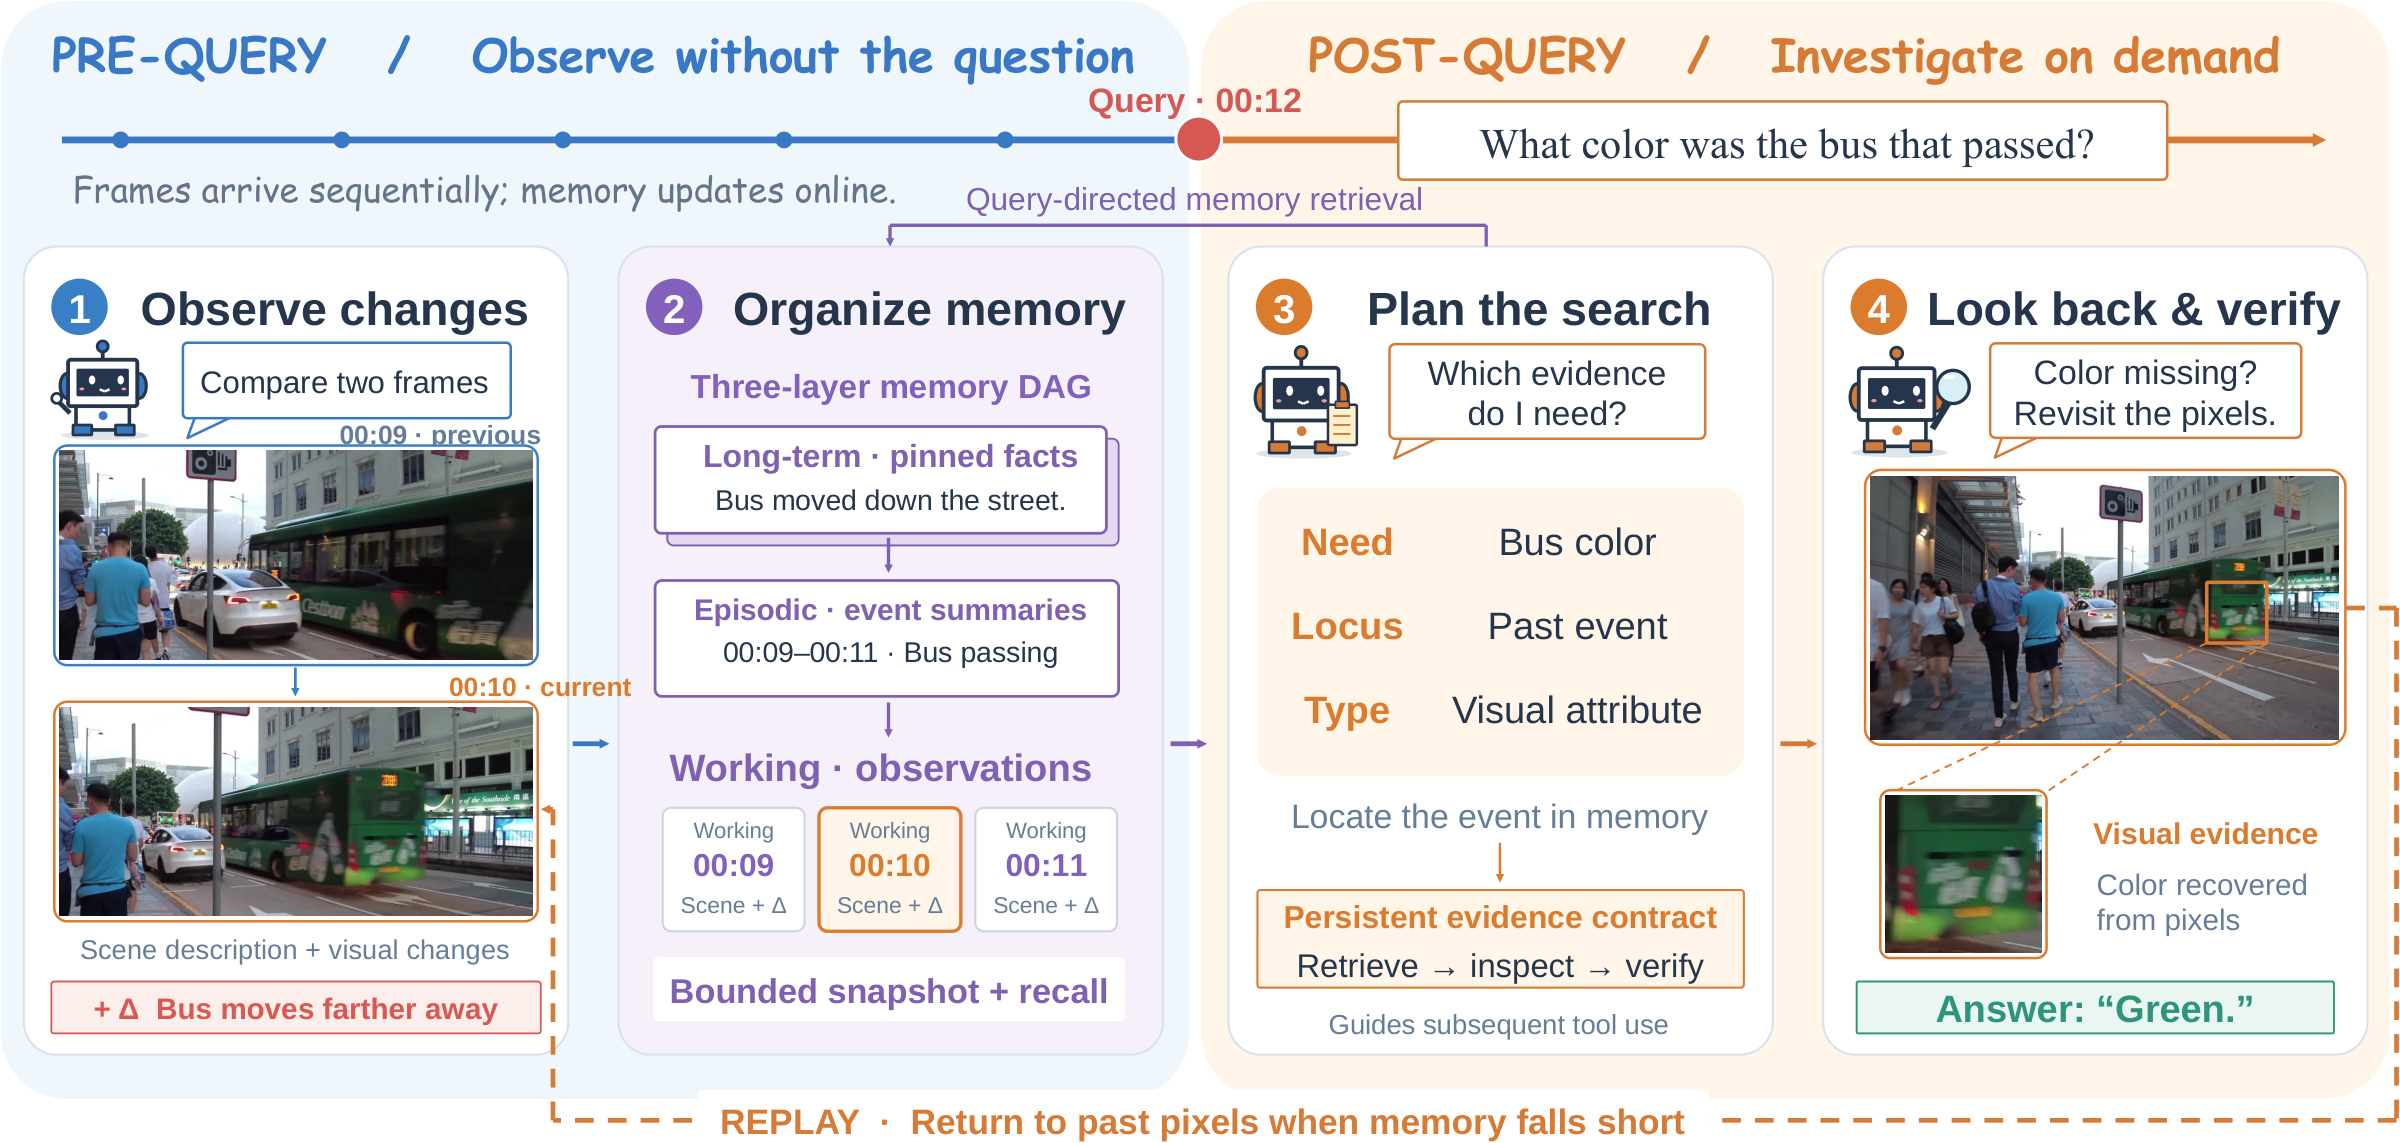
DeltaStreamer: Towards Human-Like Agentic Streaming Video Understanding
An agent connects change-aware memory with question-driven planning and visual replay for streaming video understanding.
GeoWeaver: Grounding Visual Tokens with Geometric Evidence before Scene Reasoning
Token-adaptive geometric evidence grounds visual representations before language-based spatial and temporal reasoning.
RCoT-Seg: Reinforced Chain-of-Thought for Video Reasoning and Segmentation
A reinforced video-of-thought framework separates temporal reasoning and keyframe selection from spatial target segmentation.
SGAFuse: Semantic-guided adaptive fusion for RGB-thermal images via dynamic gating
Semantic guidance and dynamic gating adapt RGB-thermal image fusion to the content of each scene.
Fusing in 3D: Free-Viewpoint Fusion Rendering with a 3D Infrared-Visible Scene Representation
A Gaussian scene representation combines infrared and visible inputs to render fused images from new viewpoints.
2025
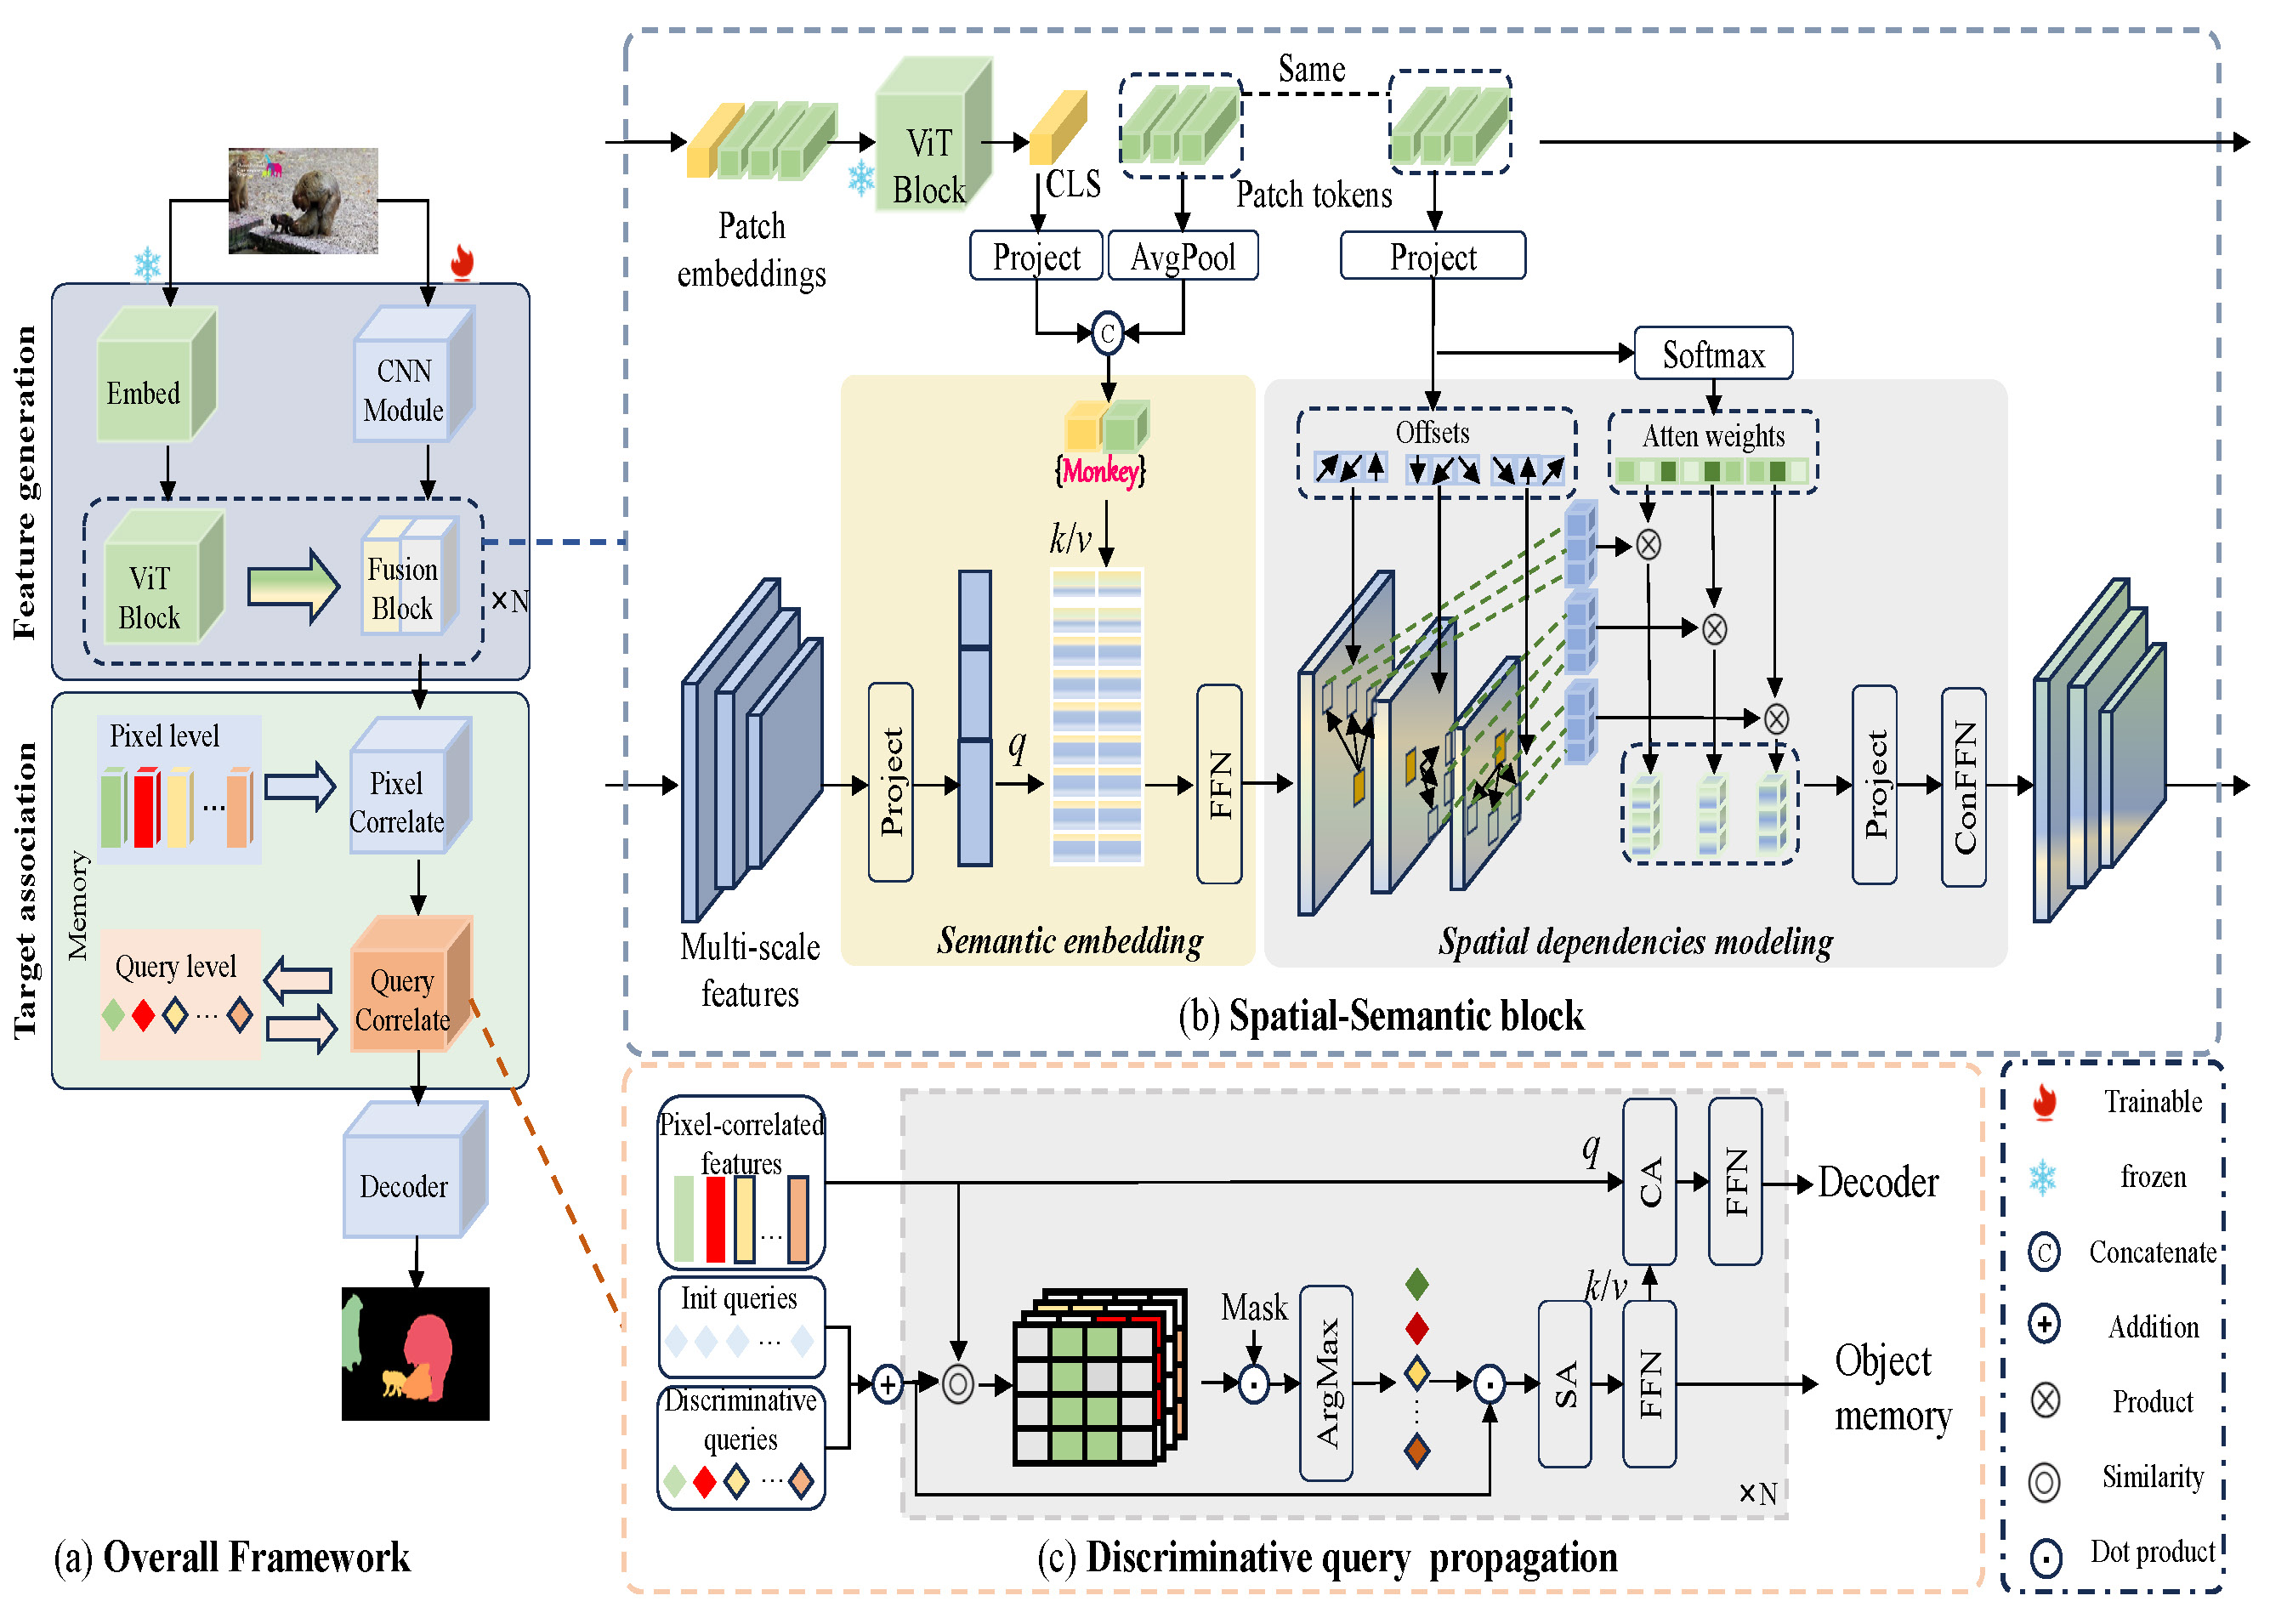
Learning Spatial-Semantic Features for Robust Video Object Segmentation
Spatial-semantic features and discriminative object queries support robust target representation and long-term video object segmentation.
2024
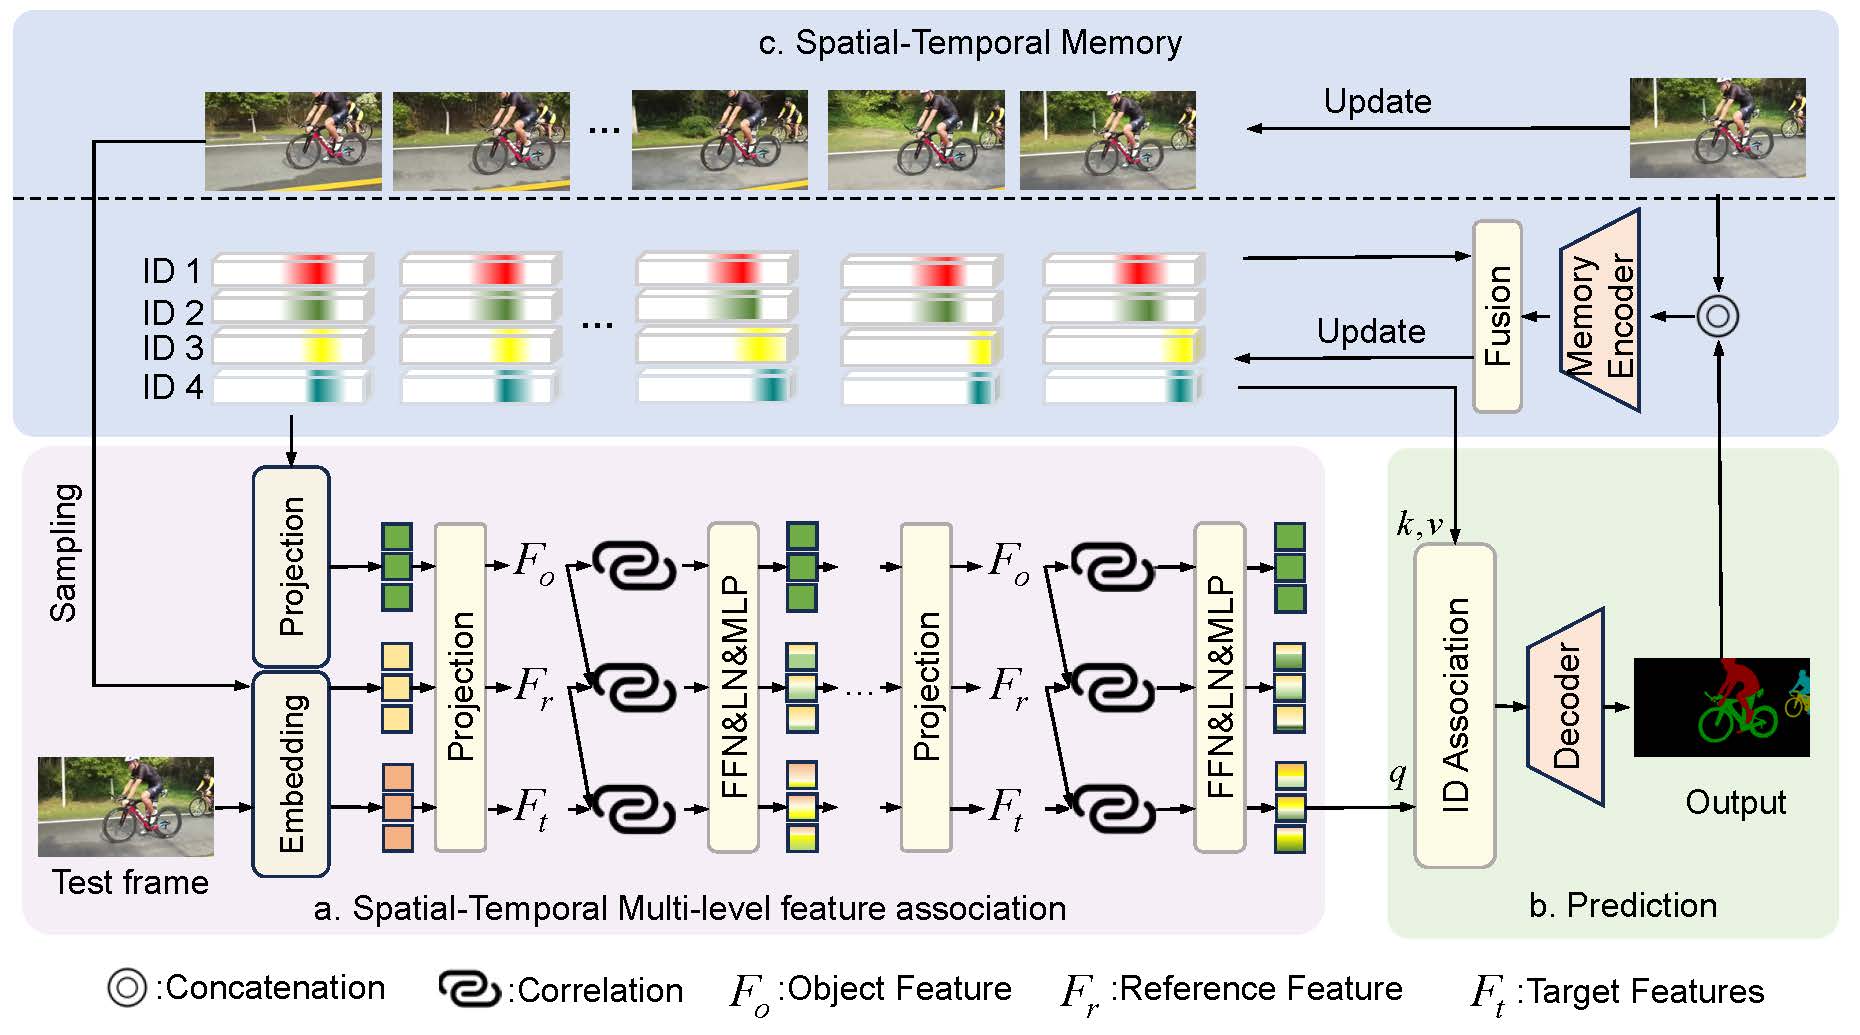
Spatial-Temporal Multi-level Association for Video Object Segmentation
Spatial-temporal memory supports feature association and consistent target identity across video frames.
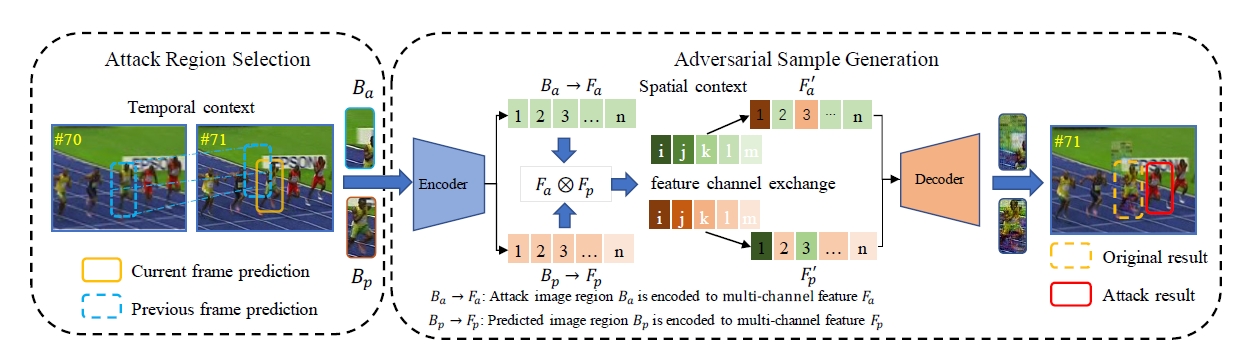
Context-Guided Black-Box Attack for Visual Tracking
A context-guided black-box attack studies the robustness of deep trackers under spatial and temporal interference.
Earlier research manuscript
Referring and Reasoning Segmentation via Learning Contextual Instructions
ContextSeg studies contextual spatial information and temporal aggregation for referring and reasoning segmentation.
🧩 Projects
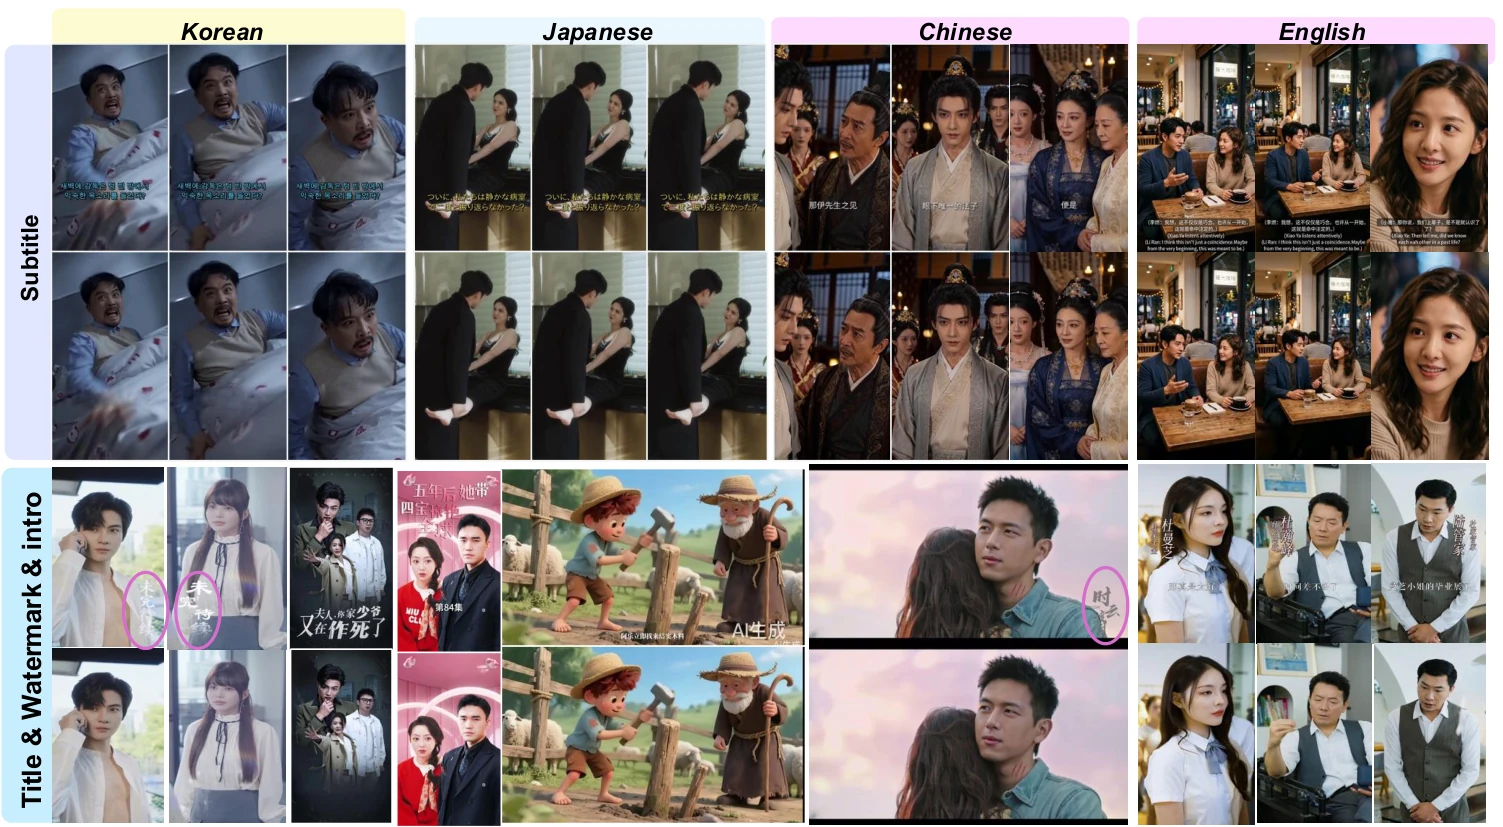
ReST
One-Step Video Subtitle Erasure · ByteDance
Residual spatio-temporal diffusion removes video subtitles while retaining source appearance and motion.
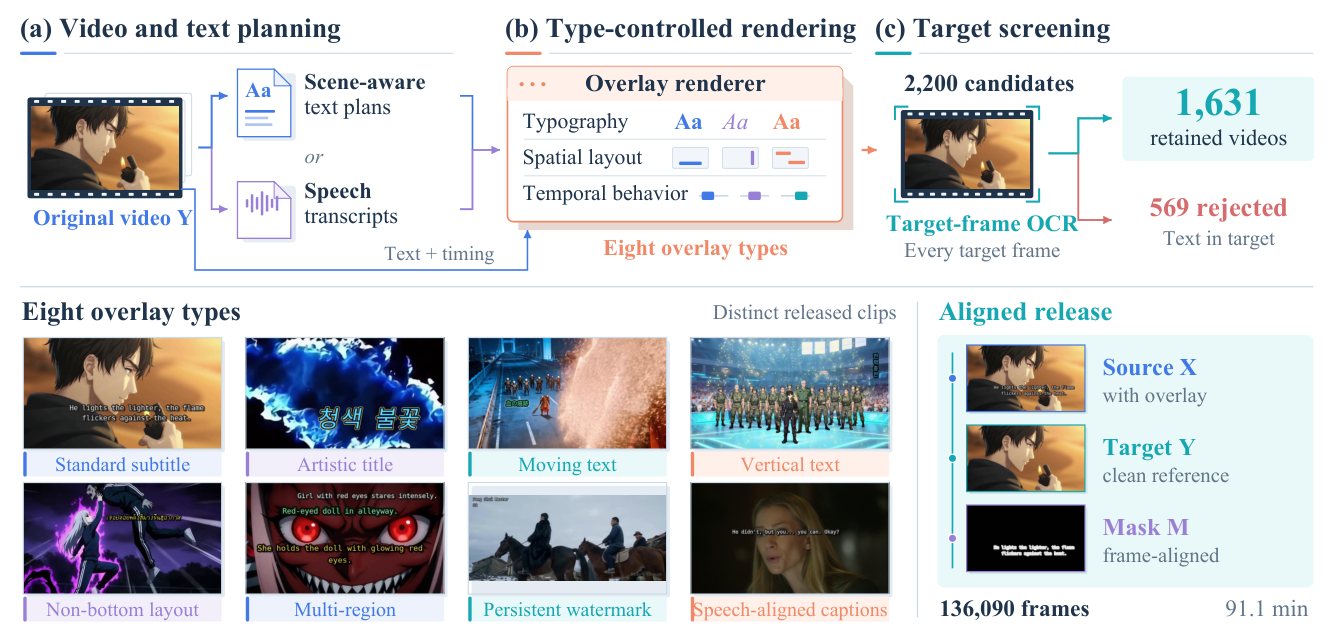
DeOverlay + DVTE-Bench
Video Overlay Removal
Explore paired videos and recorded removal results across eight text-overlay categories, with 1,631 clips and 136,090 frames.
📄 Technical Reports
- APRVOS: 1st Place Winner of 5th PVUW MeViS-Audio Track
An audio-conditioned referring video segmentation pipeline combines transcription, visual presence verification and agent-guided mask refinement.
- AgentRVOS for MeViS-Text Track of 5th PVUW Challenge: 3rd Method
A multi-agent loop verifies target presence, searches temporal evidence and refines Sa2VA video masks with SAM3.
- OAMVOS:2nd Report for 5th PVUW MOSE Track
Reliability-aware memory control and branch recovery improve SAM-based video tracking under occlusion and reappearance.
- Report of the 5th PVUW Challenge: Towards More Diverse Modalities in Pixel-Level Understanding
The CVPR 2026 PVUW overview compares solutions across MOSE, MeViS-Text and the new MeViS-Audio track.
🏆 Honors and Awards
- 2026 · CVPR PVUW — MeViS-Audio track, 1st place. APRVOS report · Official workshop
- 2025 · VOTS Challenge — Winner, VOTS / VOTS-RT / VOTSt tracks.
- 2024 · 6th LSVOS Challenge — VOS track, 1st place. Report · Certificate
- 2024 · VOTS Challenge — VOTS track, Winner. Challenge report · Certificate
- 2024 · CVPR PVUW — MOSE track, 1st place. Report · Certificate
- 2023 · ICCV 5th LSVOS Challenge — VOS track, 2nd place. Report · Certificate
🎖 Services
Reviewer: NeurIPS 2024.
💻 Internships
- 2025.10 – Present · ByteDance, Algorithm Research Intern, Shenzhen, China.
- 2025.05 – 2025.08 · Tencent, Qingyun Program (青云计划), Shenzhen, China.
- 2022.09 – 2025.04 · Peng Cheng Laboratory, supervised by Xin Li, Shenzhen, China.
- 2021.07 – 2022.05 · Alibaba AI Research (Amap), Beijing, China.
- 2021.05 – 2021.07 · SenseTime, Beijing, China.