 ByteDance
Source-Anchored Residual
Uses the structured source latent as the starting point and predicts the complete source-to-clean endpoint correction.
Video Subtitle Erasure
Residual Spatio-Temporal Diffusion for One-Step Video Subtitle Erasure
ByteDance
Abstract
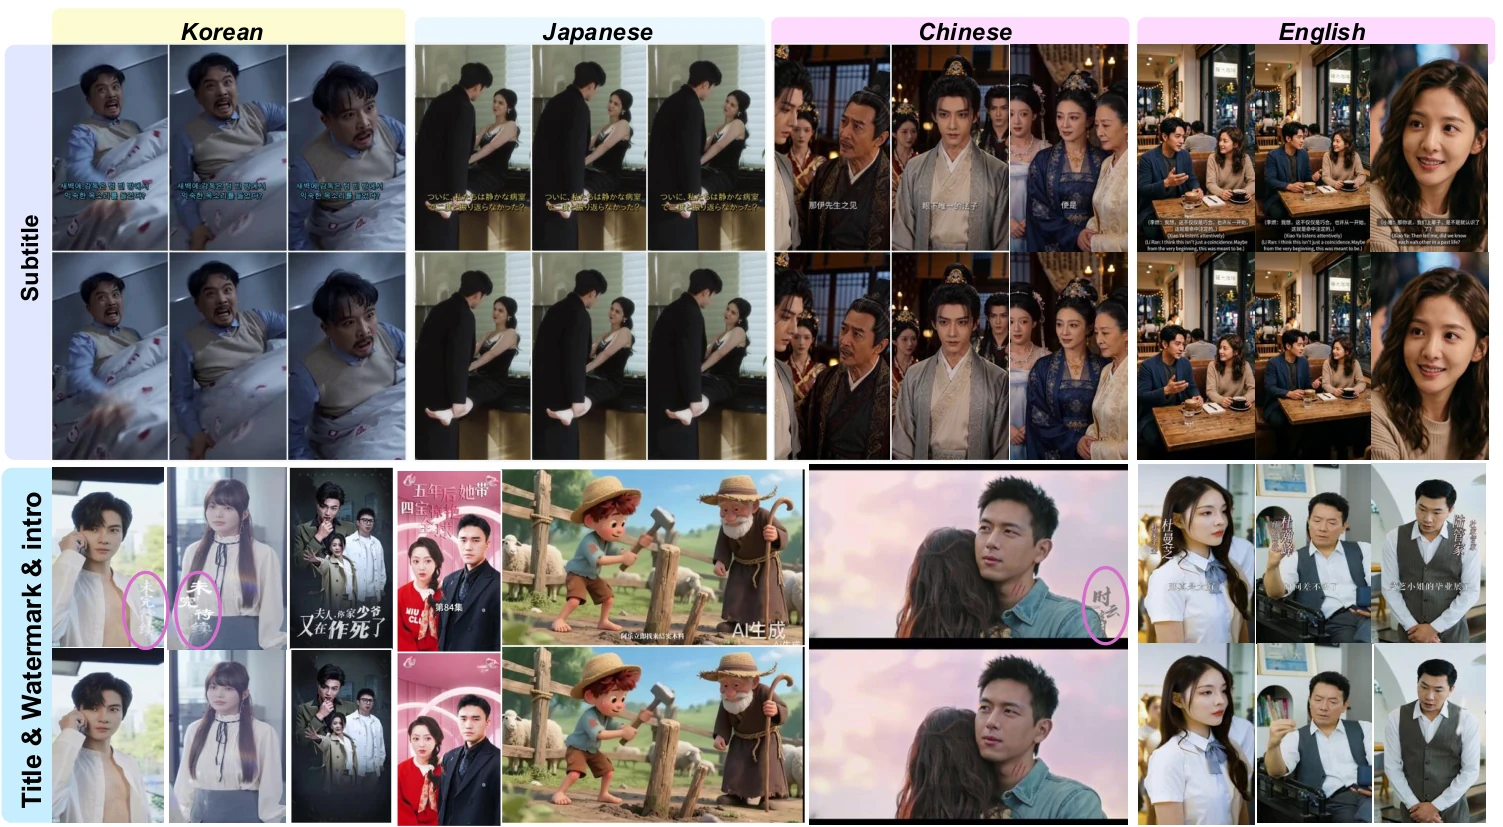
Video subtitle erasure requires removing overlaid text while faithfully preserving spatio-temporal content. Existing inpainting methods treat the affected area as a hole, discarding useful evidence that survives beneath translucent glyphs, shadows, and antialiased boundaries.
ReST instead anchors editing at the subtitled source latent and predicts the complete source-to-clean residual in one model evaluation. Masked Temporal Evidence Aggregation retrieves uncontaminated observations from nearby frames, while Global Appearance Conditioning maintains clip-level illumination and color. Region-aware latent and RGB supervision recovers fine text boundaries, and conservative composition limits synthesis to subtitle-affected regions when localization is available.
Method
Most pixels are already correct. ReST predicts only the localized correction instead of regenerating the full video from Gaussian noise.
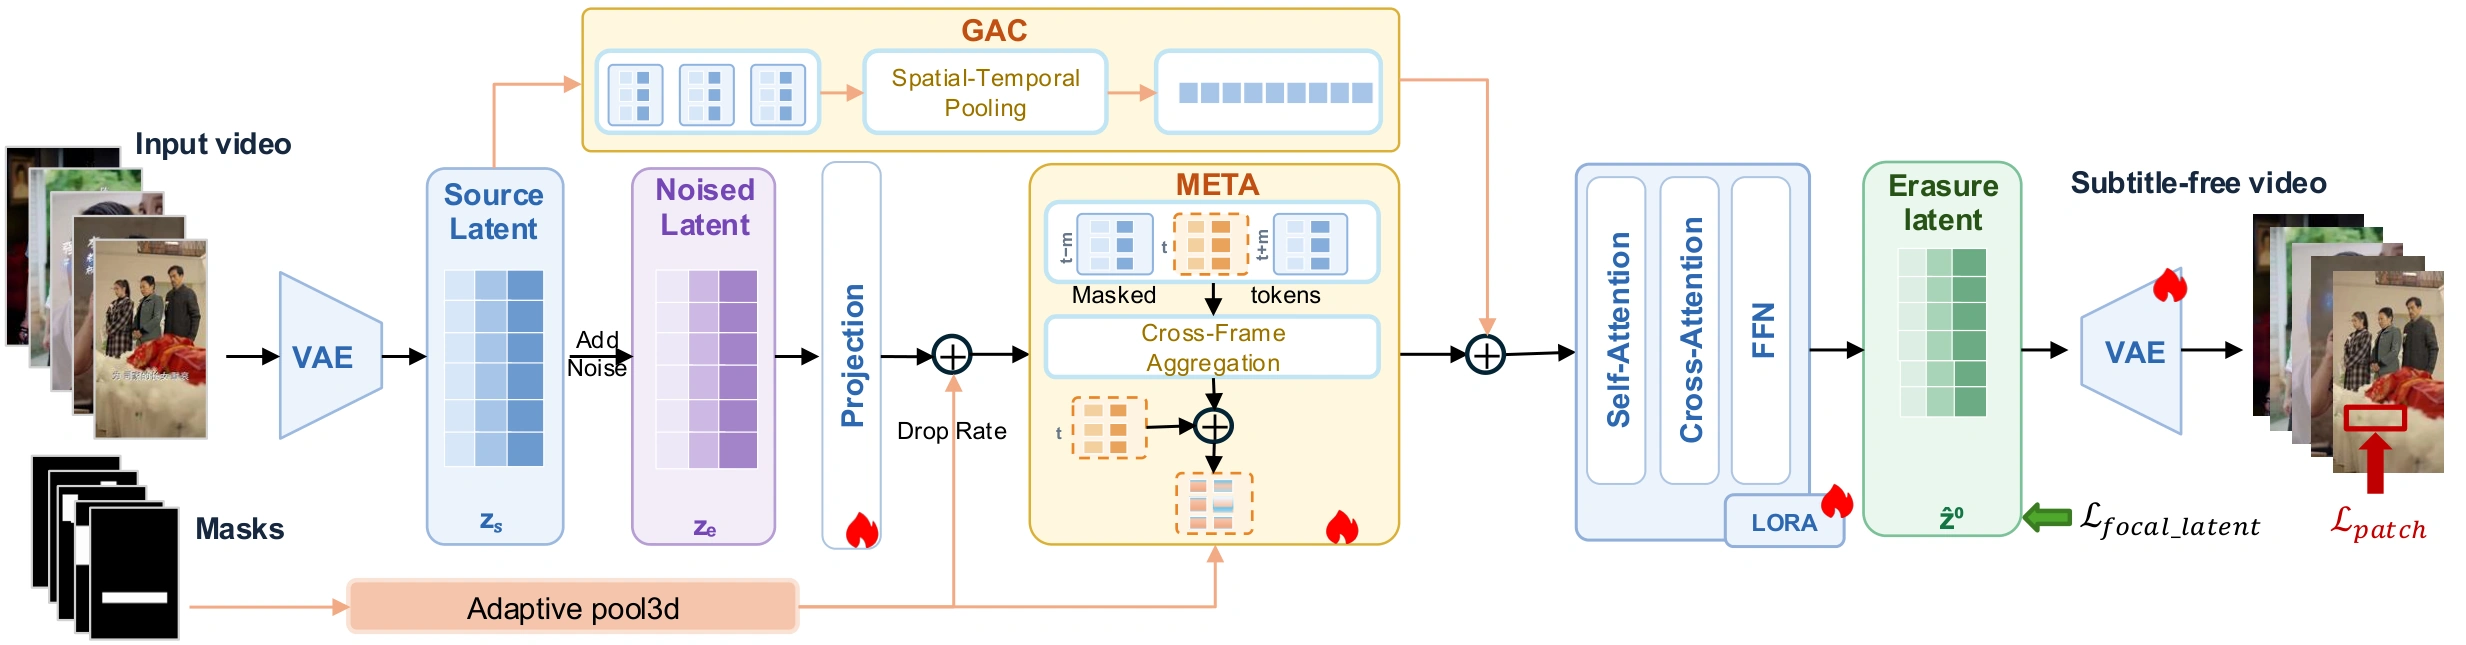
Uses the structured source latent as the starting point and predicts the complete source-to-clean endpoint correction.
MTEA aggregates only visible, uncontaminated observations in a normalized five-frame window.
GAC broadcasts a pooled clip descriptor to keep restored content consistent in color and illumination.
Weighted latent learning and localized RGB patch decoding recover thin strokes, outlines, and shadows.
Shot-aware chunks, overlap blending, and optional conservative paste-back prevent drift over long sequences.
Results
Watch the narrated overview, then explore individual restoration cases in the interactive gallery below.
Interactive Gallery
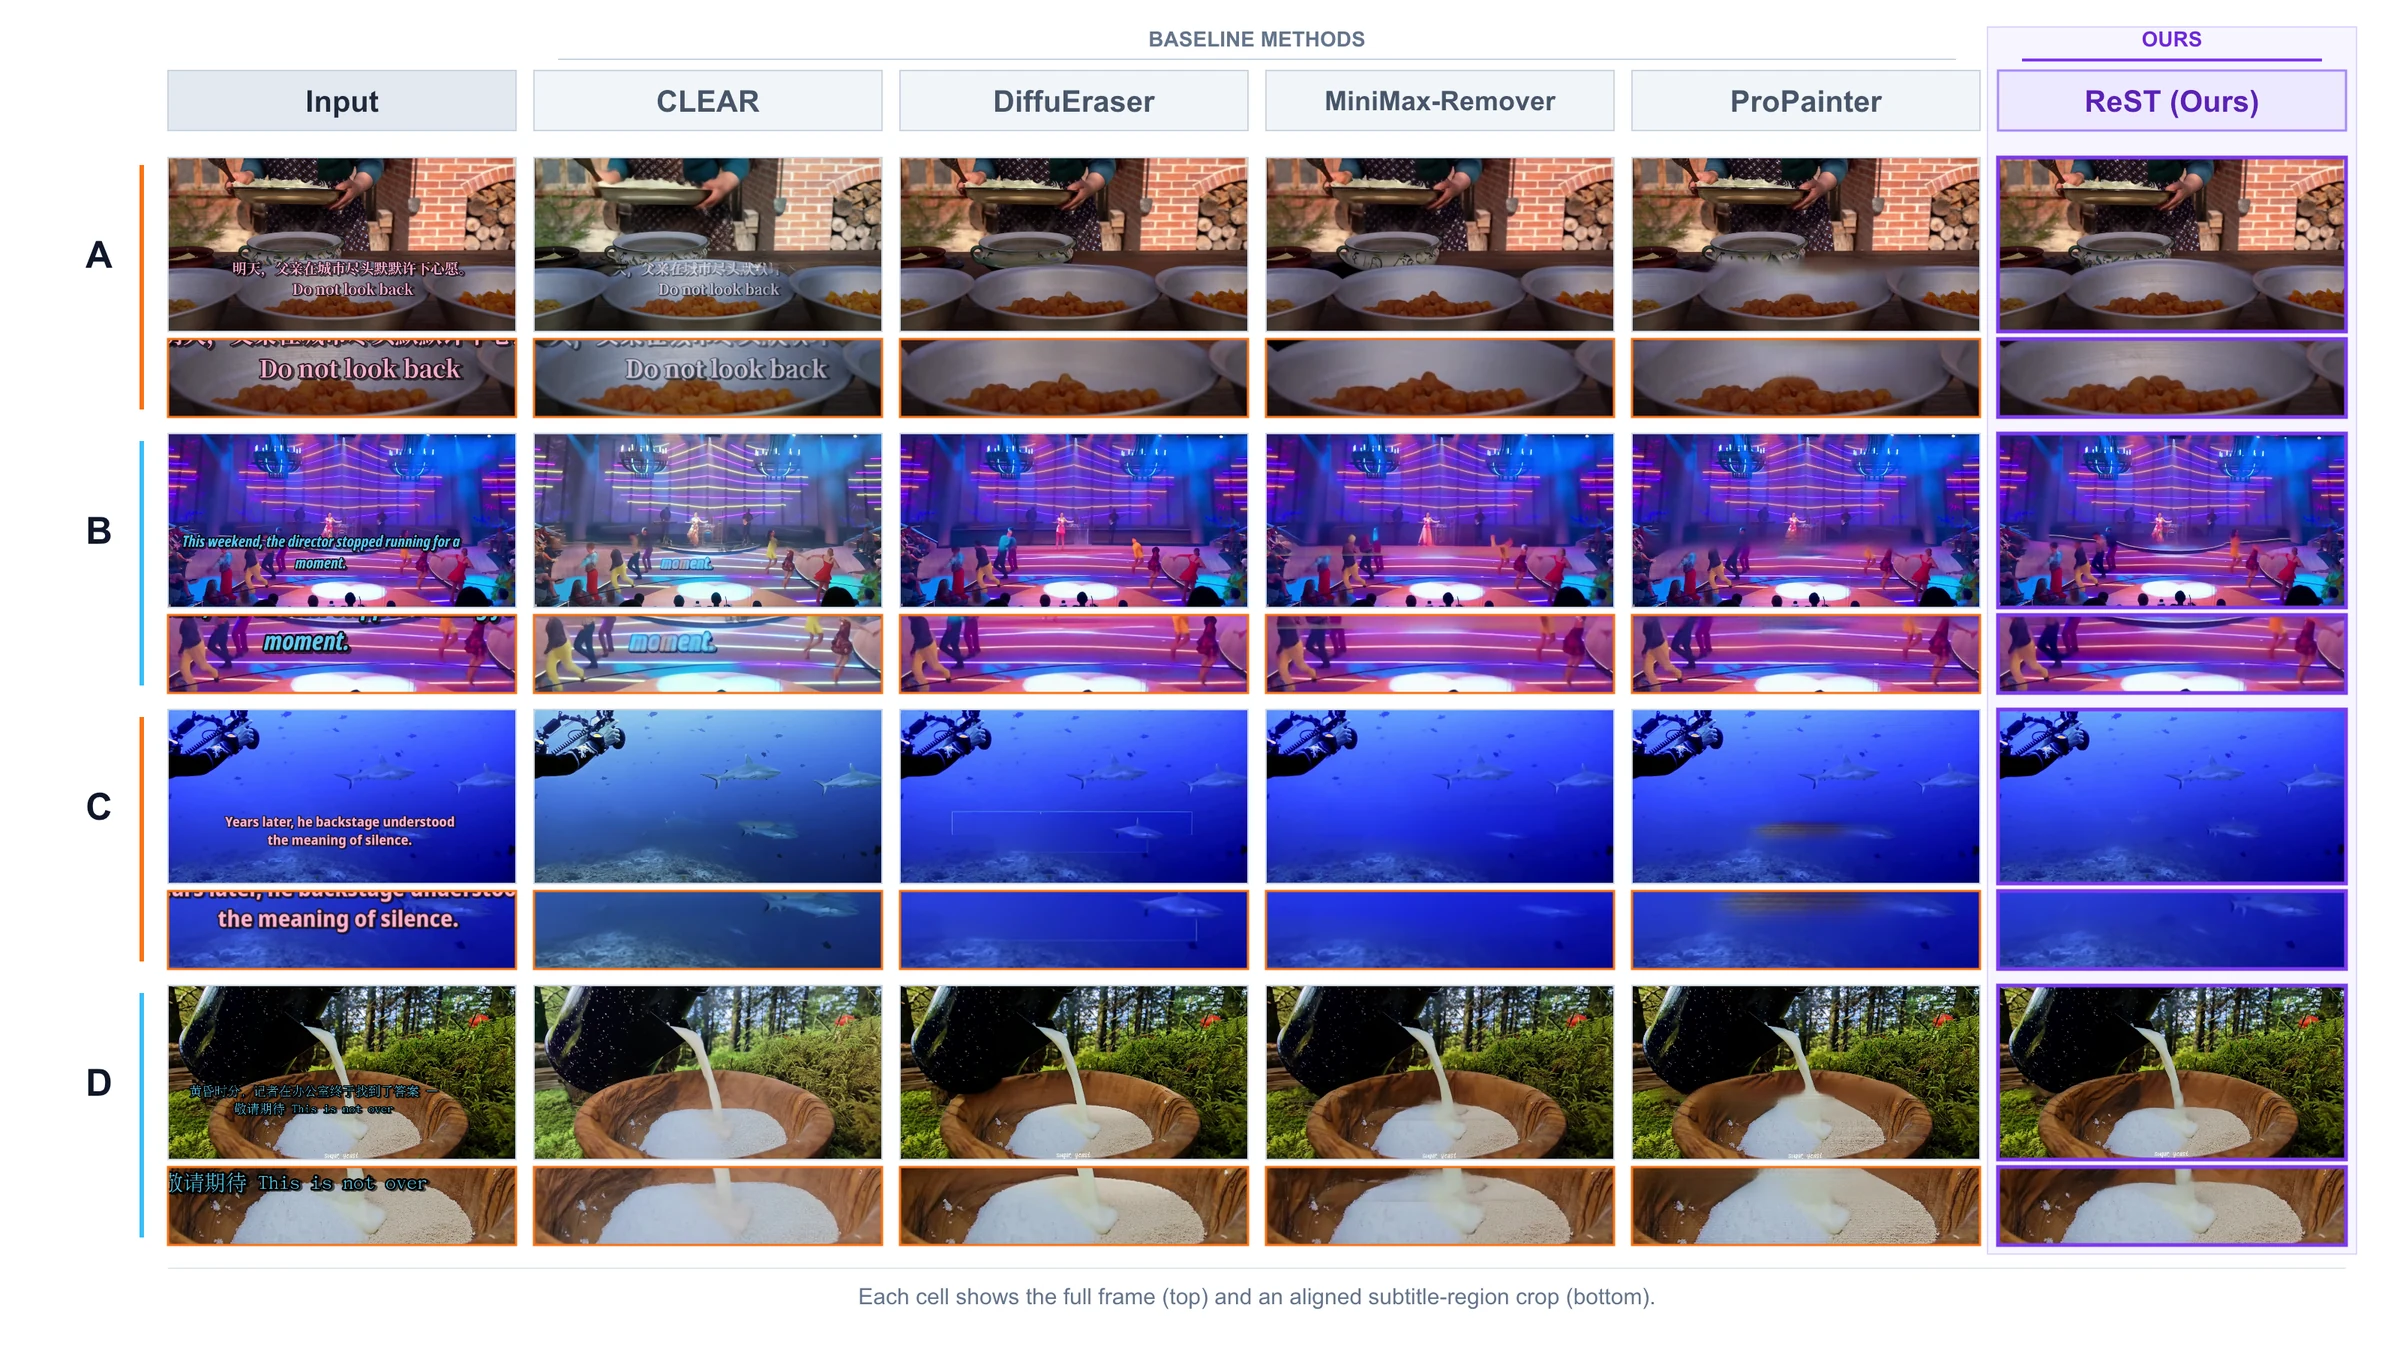
Hover to preview comparison clips ranging from 6 to 15 seconds. Select a case to inspect it in the focus player, or leave auto-cycle on to let the gallery move through the collection.
Real-world case
Dense dialogue and stylized overlays.
Preview clips are compressed from the local comparison videos for fast browsing. The full narrated demo remains available above.
Benchmark
Paired Chinese-English subtitle benchmark, 200 videos. Best values are highlighted.
| Method | PSNR ↑ | SSIM ↑ | LPIPS ↓ | VFID ↓ | Flow Mean ↓ | s/frame ↓ |
|---|---|---|---|---|---|---|
| CLEAR | 21.02 | 0.77 | 0.20 | 3.12 | 0.22 | 0.85 |
| ProPainter | 28.06 | 0.87 | 0.15 | 1.89 | 0.09 | 0.12 |
| MiniMax-Remover | 27.27 | 0.85 | 0.16 | 1.69 | 0.15 | 0.35 |
| DiffuEraser | 28.00 | 0.89 | 0.13 | 1.52 | 0.10 | 0.44 |
| ReST Ours | 34.01 | 0.95 | 0.05 | 0.41 | 0.07 | 0.03 |
+5.09 dB over ProPainter inside the edited region.
45.2% lower masked error than ProPainter.
N video tokens and 6 days, versus 2N tokens and 15 days.
Deployment
No localization required
The model jointly identifies and removes subtitles from the complete source observation. Long-video chunks are joined using overlap blending.
Strict background identity
A supplied localization prior activates MTEA and conservative feathered paste-back, copying source pixels outside subtitle neighborhoods.
Citation
Cite the project page when referencing ReST results, videos, or implementation details.
@misc{rest_project,
  title     = {ReST: Residual Spatio-Temporal Diffusion for
               One-Step Video Subtitle Erasure},
  organization = {ByteDance},
  howpublished = {\url{https://yahooo-m.github.io/ReST/}},
  year      = {2026}
}